Ziyang WangI am a fifth year CS Ph.D. candidate at The University of North Carolina, Chapel Hill advised by Prof. Mohit Bansal and also work closely with Prof. Gedas Bertasius. My research focuses on multimodal AI and agentic systems for understanding and reasoning across different modalities (especially videos). My goal is to develop effective and efficient systems that integrate perception and reasoning to solve complex real-world problems. In summer 2026, I was a Data Science Fellow and Research Intern at Bloomberg working with Dr. Debanjan Mahata and Dr. Daniel Preoțiuc-Pietro on large-scale multimodal document understanding. Previously, I worked as a research intern at Salesforce AI Research (manager: Dr. Juan Carlos Niebles, also working with Dr. Michael S. Ryoo, Dr. Junnan Li, and Dr. Honglu Zhou) on agentic long video understanding. I worked as a research intern at Meta, FAIR Perception team in 2024 (managers: Dr. Ronghang Hu, and Dr. Christoph Feichtenhofer, also working with Dr. Po-Yao Huang and Dr. Daniel Bolya). Previously, I was an Applied Scientist Intern in Amazon Alexa AI working with Dr. Heba Elfardy, Dr. Kevin Small, Dr. Markus Dreyer. I also interned in Tsinghua AIR working with Prof. Jingjing Liu. I finished my undergrad study at UESTC and advised by Prof. Jingjing Li. My email address is ziyangw at cs . unc . edu, if you have any questions, feel free to contact me! Google Scholar / Curriculum Vitae / GitHub / Linkedin / Twitter |
|
ResearchIn general, I am interested in building multimodal systems that perceive and reason over long and complex videos. My recent work includes agentic video understanding (Searching Videos as Trees, NeurIPS 2026; Active Video Perception, CVPR 2026; VideoTree, CVPR 2025), long-horizon memory and reasoning (EgoMemReason, COLM 2026), evidence-grounded and verifiable reasoning (Evidence-Backed VideoQA, ECCV 2026; Multimodal Fact-Level Attribution, ICML 2026), RL + test-time scaling (Video-RTS, EMNLP 2025), and LLM-based video understanding (LLoVi, MEXA, SiLVR). Earlier, I worked on video-text retrieval (UCoFiA, ICCV 2023) and zero-shot learning. |
|
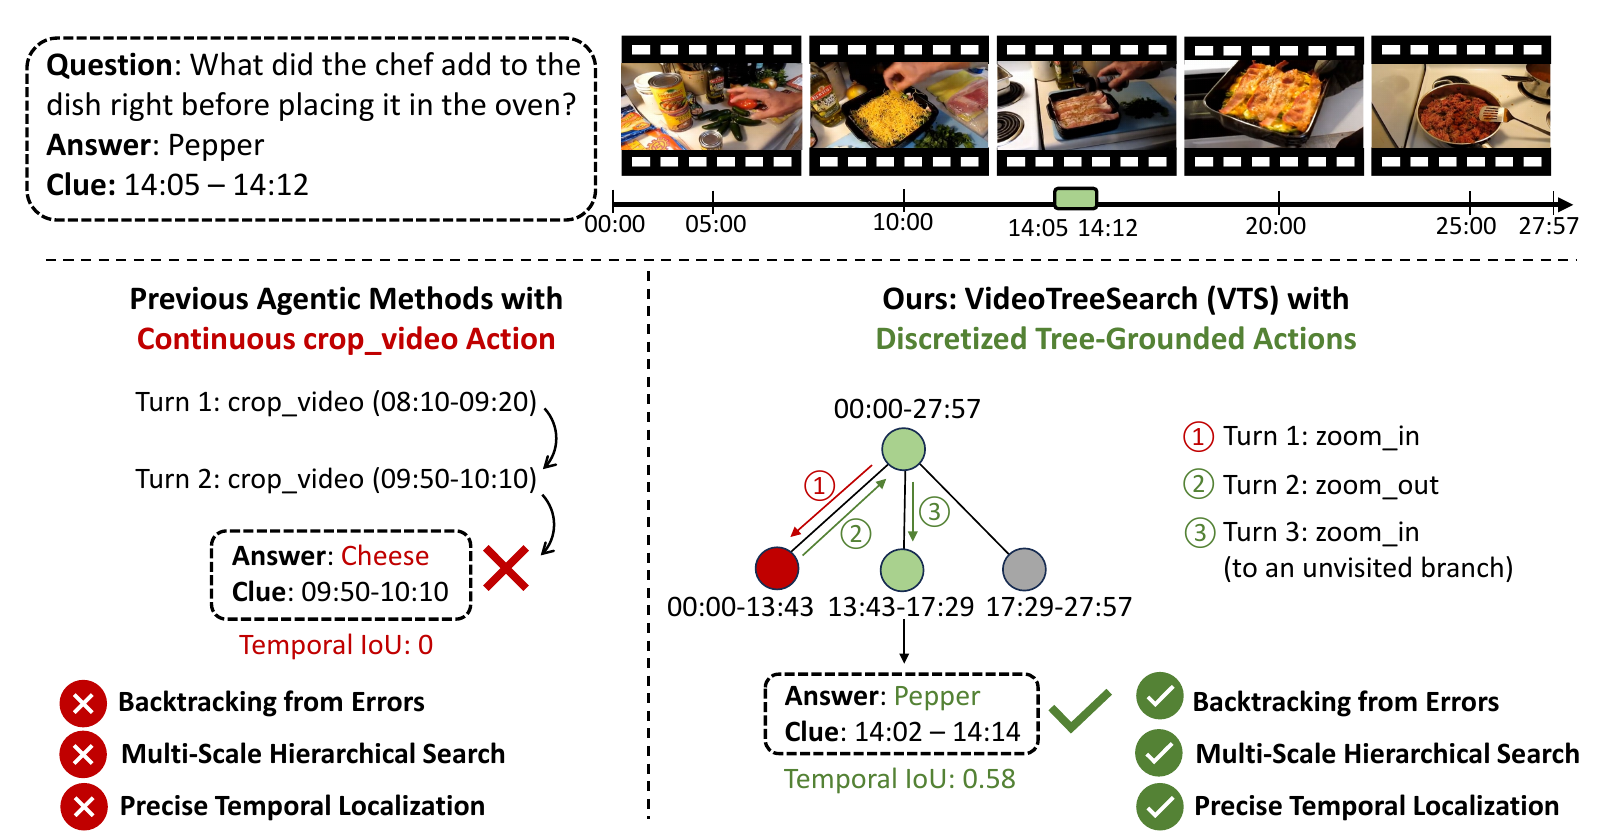
Searching Videos as Trees: Self-Correcting Agents for Grounded Long Video QACe Zhang, Ziyang Wang, Yulu Pan, Oluwatumininu Oguntola, Pranav Wagh, Qiyu Wu, Hiromi Wakaki, Mohit Bansal, Gedas Bertasius NeurIPS 2026 arxiv / code / We propose VideoTreeSearch (VTS), which casts grounded long video QA as iterative self-correcting search over an adaptive temporal tree built from visual scene boundaries. An agent navigates the tree with discrete zoom_in, zoom_out, shift, and answer actions, making backtracking and recovery explicit, learnable primitives. VTS outperforms the strongest prior agentic methods by +12.5 mIoU on CG-Bench and +7.4 T-F1 on Haystack-Ego4D, and its learned policy transfers to general long video QA (Video-MME, MLVU, LVBench). |
|
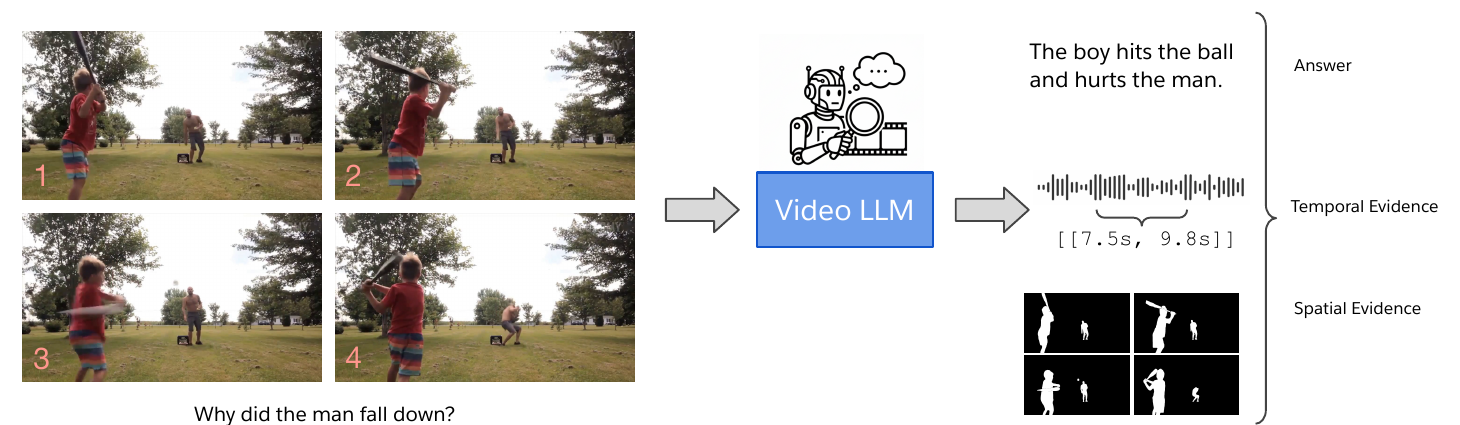
Evidence-Backed Video Question AnsweringShijie Wang, Honglu Zhou, Ziyang Wang, Ran Xu, Caiming Xiong, Silvio Savarese, Chen Sun, Juan Carlos Niebles ECCV 2026 arxiv / code / We propose Evidence-Backed Video Question Answering (E-VQA), a task requiring Video LLMs to jointly output an answer and precise spatio-temporal evidence: temporal segments and dense, tracked object segmentation masklets. We introduce ST-Evidence, the first human-verified benchmark for this setting, and ST-Evidence-Instruct, a 160k-scale training set, which yields large gains over size-matched baselines (e.g., +27.2 t-mean and +13.8 J&F on a 7B model). |
|
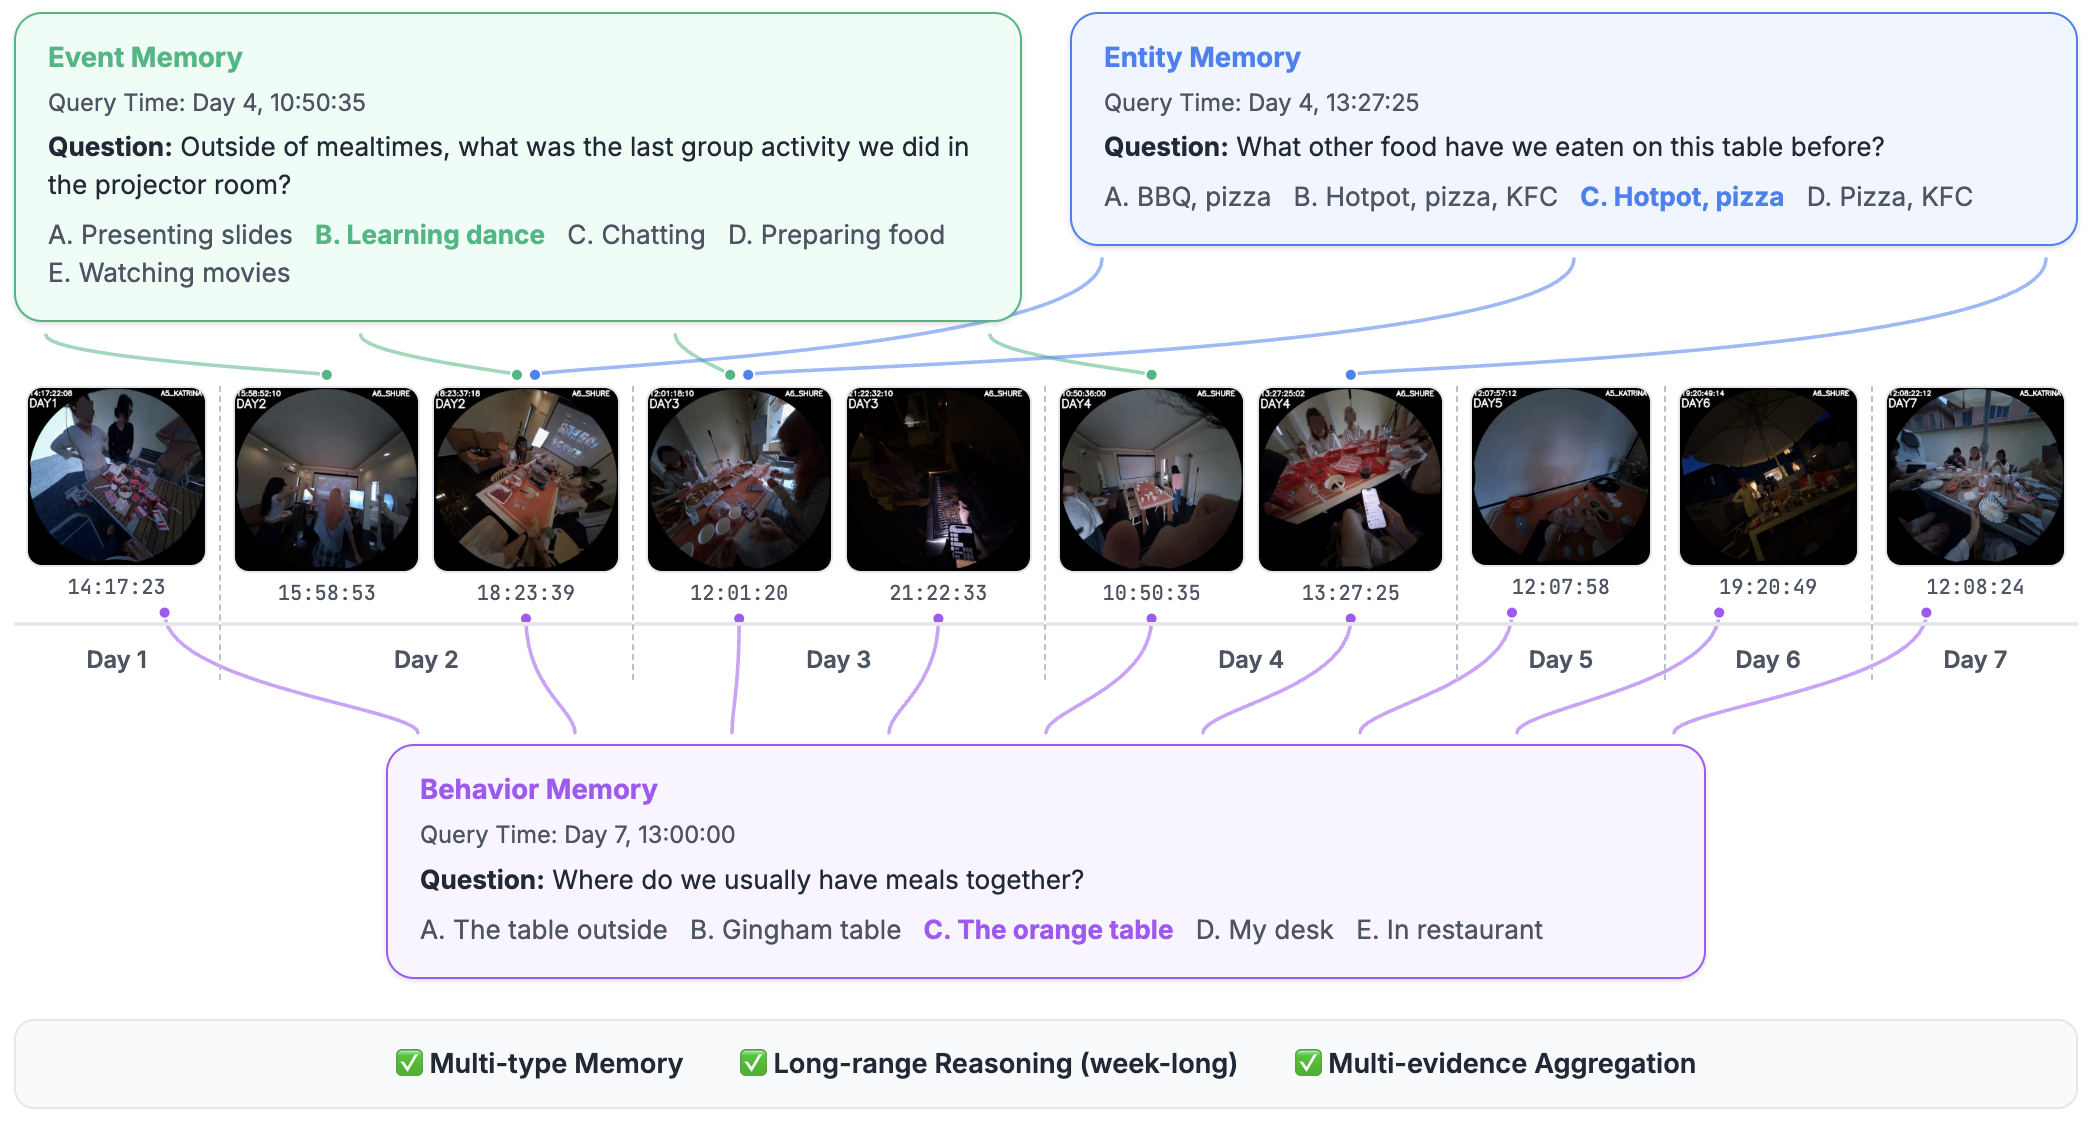
EgoMemReason: A Memory-Driven Reasoning Benchmark for Long-Horizon Egocentric Video UnderstandingZiyang Wang*, Yue Zhang*, Shoubin Yu, Ce Zhang, Zengqi Zhao, Jaehong Yoon, Hyunji Lee, Gedas Bertasius, Mohit Bansal COLM 2026 arxiv / code / EgoMemReason is a memory-driven reasoning benchmark for long-horizon egocentric video understanding, designed to evaluate how models build, retain, and reason over memory across extended first-person videos. |
|
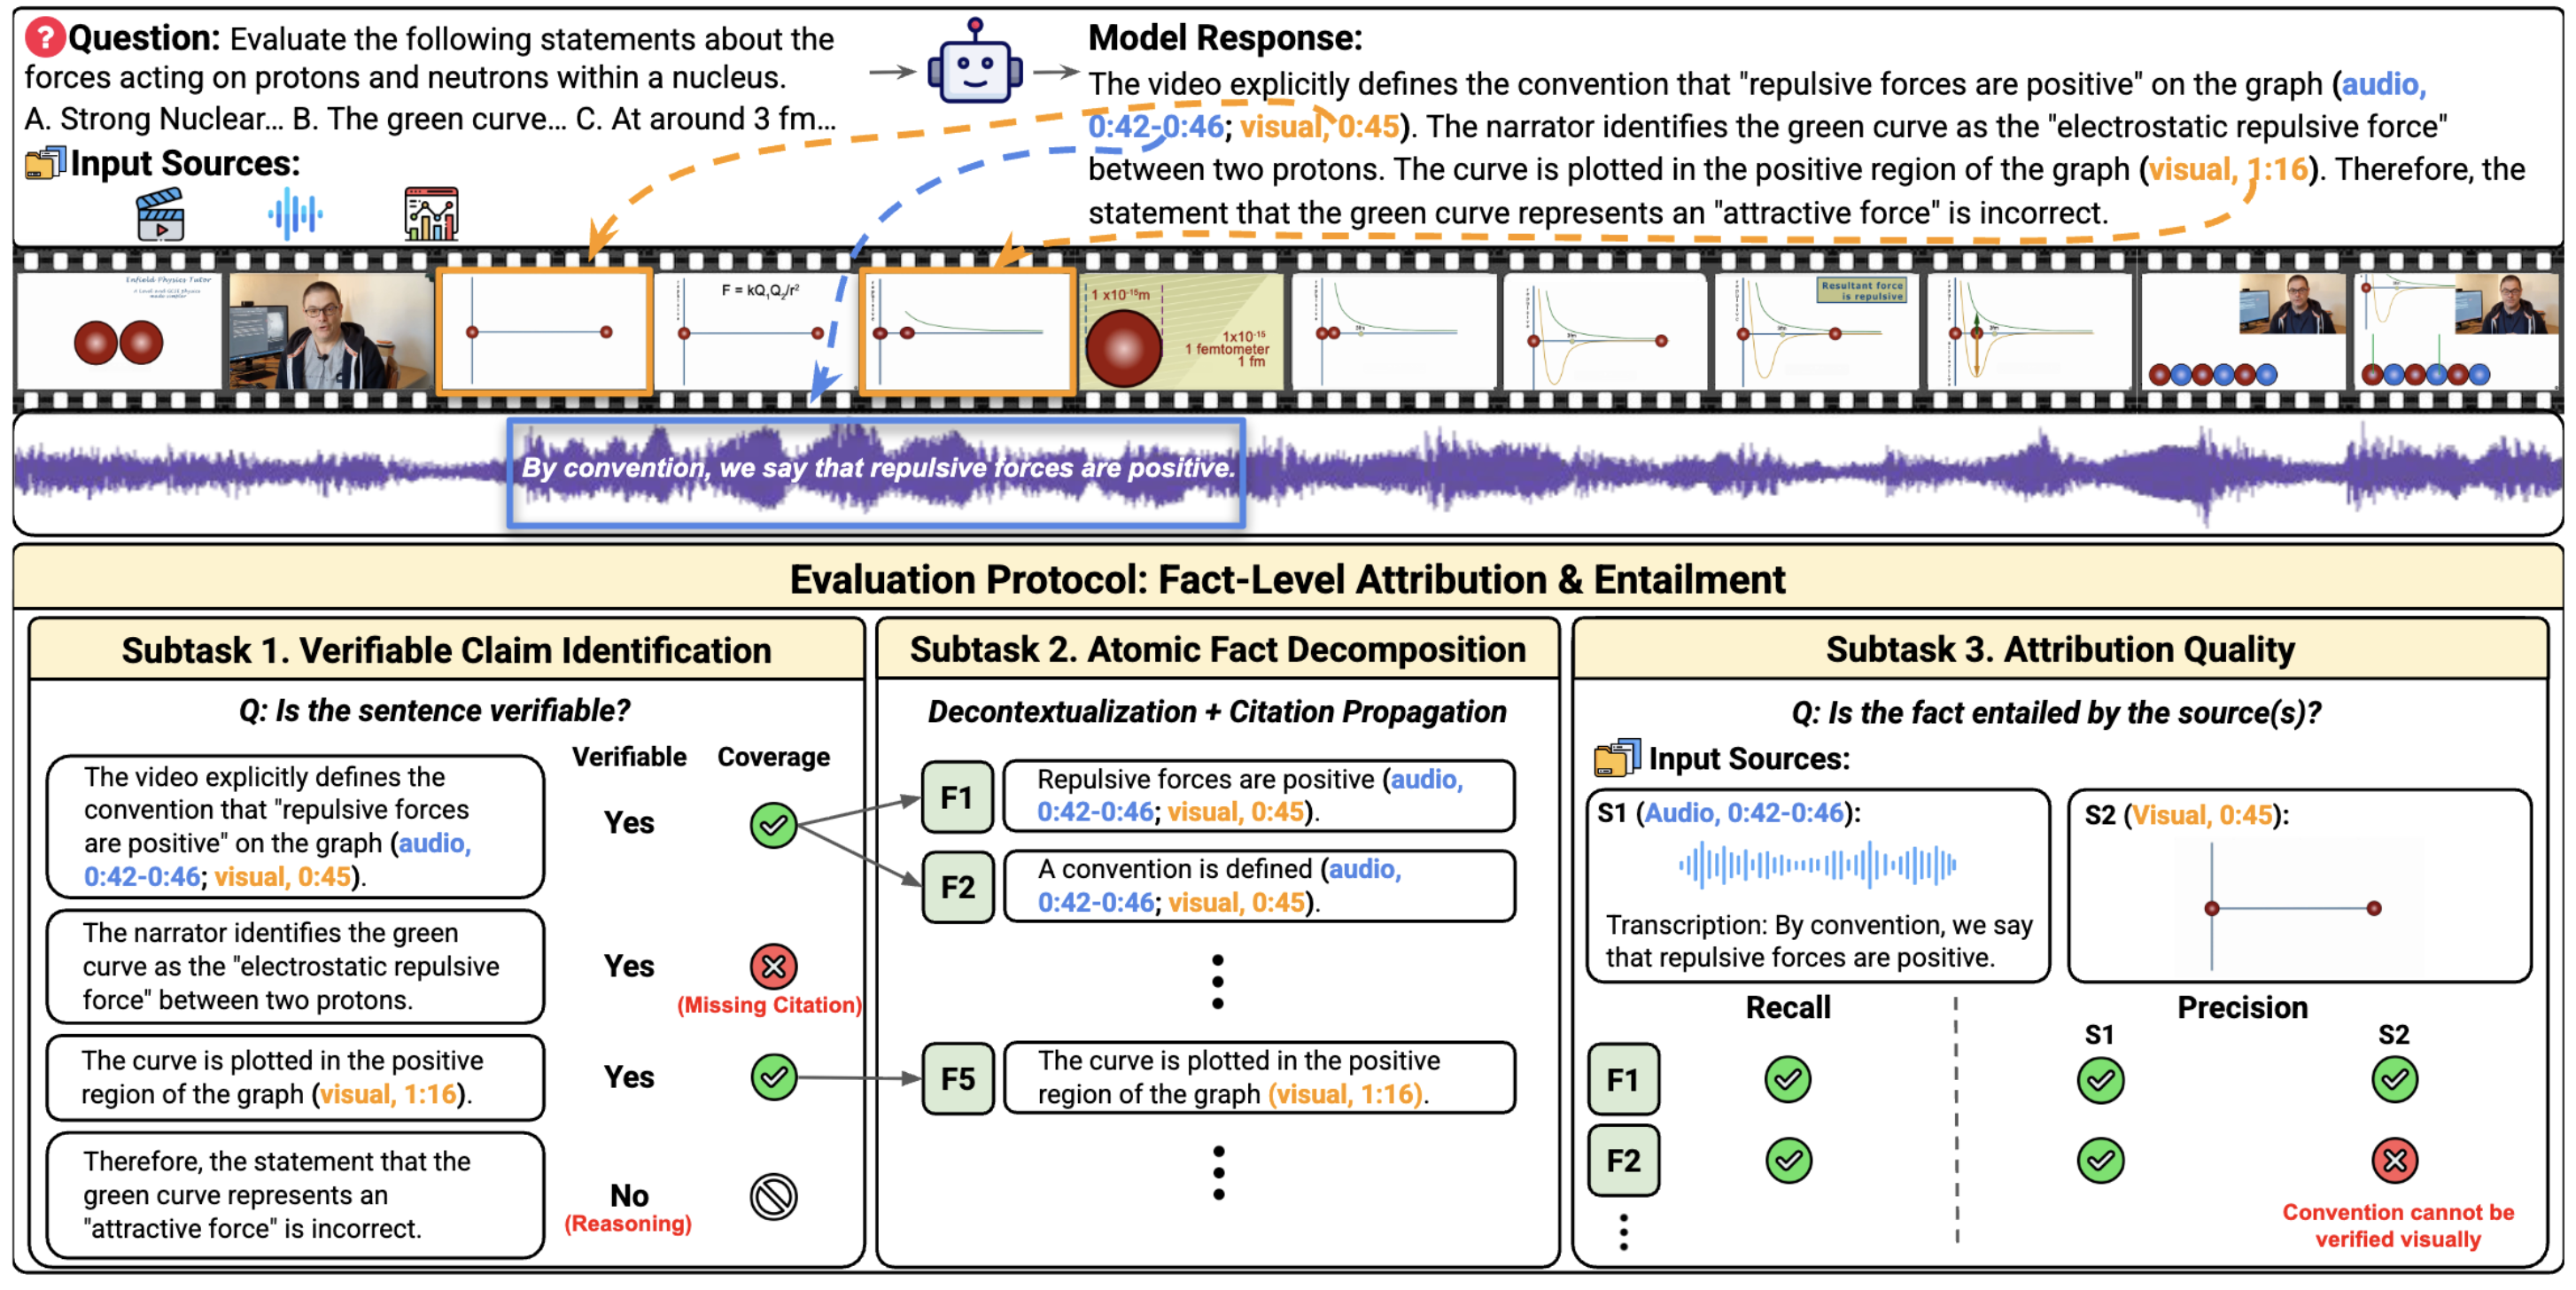
Multimodal Fact-Level Attribution for Verifiable ReasoningDavid Wan, Han Wang, Ziyang Wang, Elias Stengel-Eskin, Hyunji Lee, Mohit Bansal ICML 2026 arxiv / Multimodal Fact-Level Attribution provides fine-grained, fact-level attribution for multimodal reasoning, enabling verifiable reasoning by grounding each claim in supporting visual and textual evidence. |
|
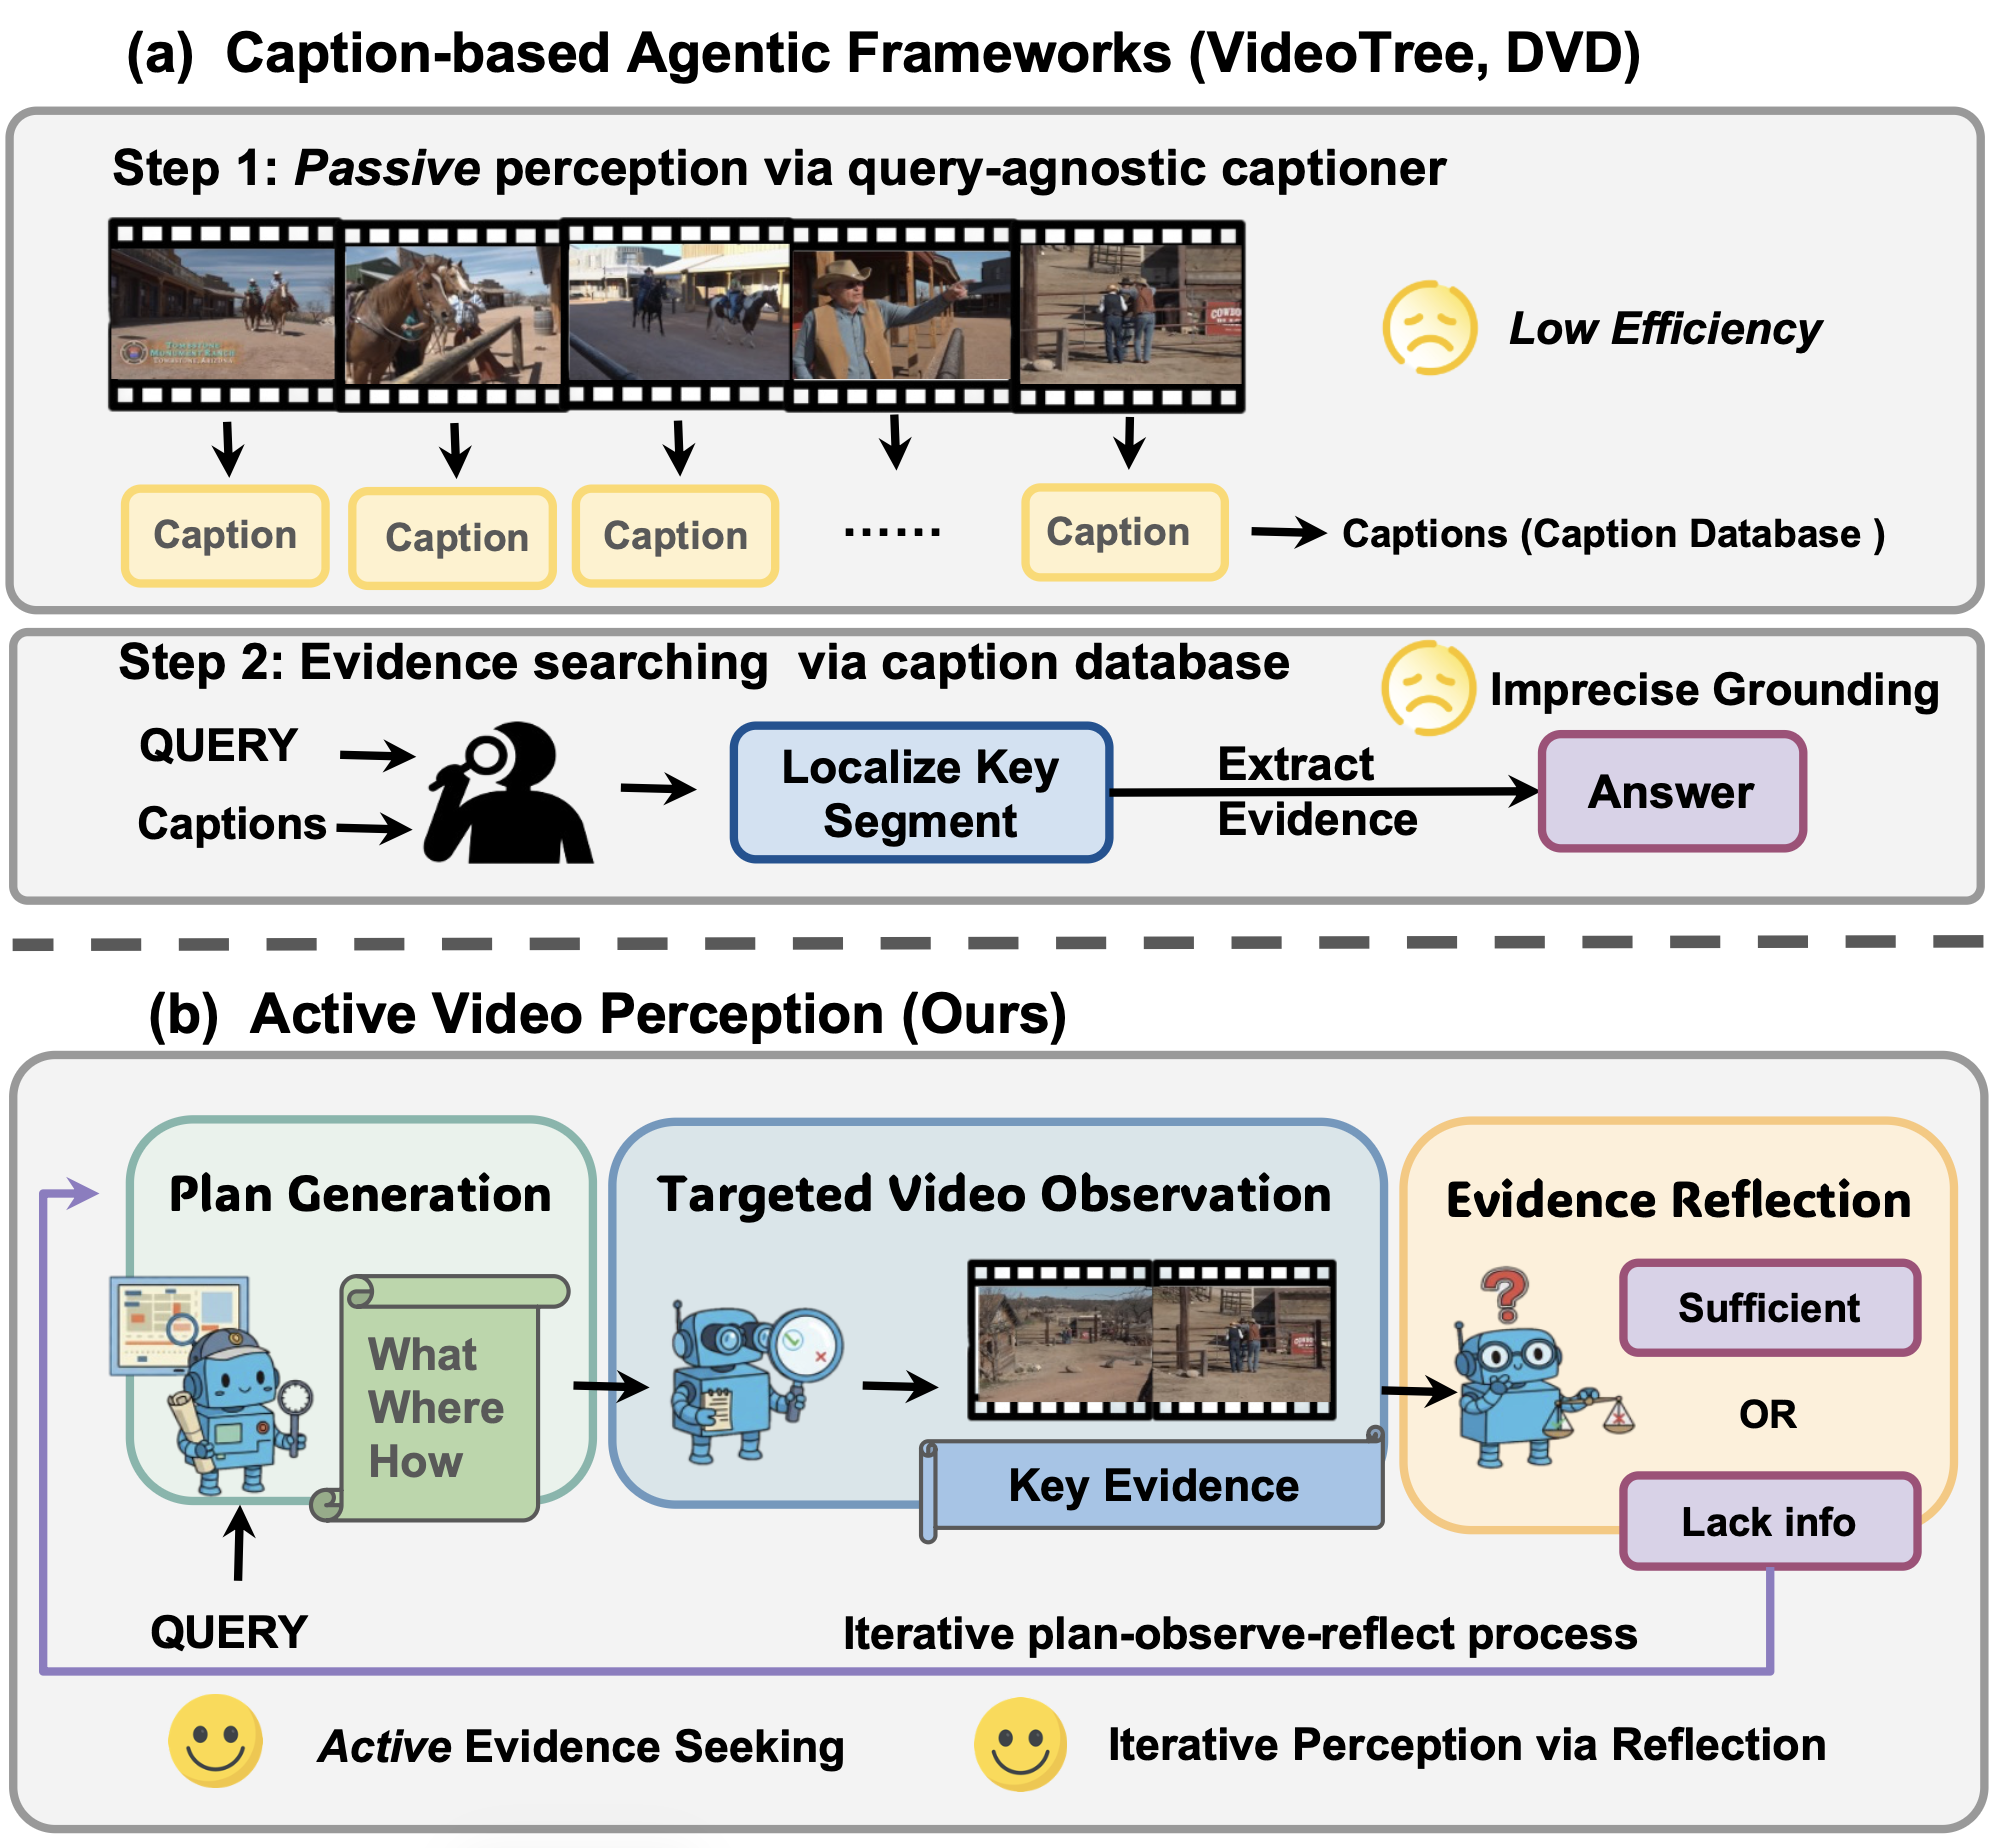
Active Video Perception: Iterative Evidence Seeking for Agentic Long Video UnderstandingZiyang Wang, Honglu Zhou, Shijie Wang, Junnan Li, Caiming Xiong, Silvio Savarese, Mohit Bansal, Michael S. Ryoo, Juan Carlos Niebles CVPR 2026 Findings arxiv / code / Inspired by active perception theory, we present Active Video Perception (AVP), which handles long video understanding as an iterative, query-driven evidence seeking process. Rather than passively caption the video frames, AVP treats the video as an interactive environment and actively decides what to inspect, where to focus, and at what granularity in order to acquire compact, time-stamped evidence directly from pixels. Concretely, AVP runs an iterative plan–observe–reflect process using MLLM agents. Empirically, AVP achieves best performance among agentic frameworks across five long video benchmarks, and surpasses the leading agentic method (DVD) by 5.7% in average accuracy while only requiring 18.4% inference time and 12.4% input tokens. |
|
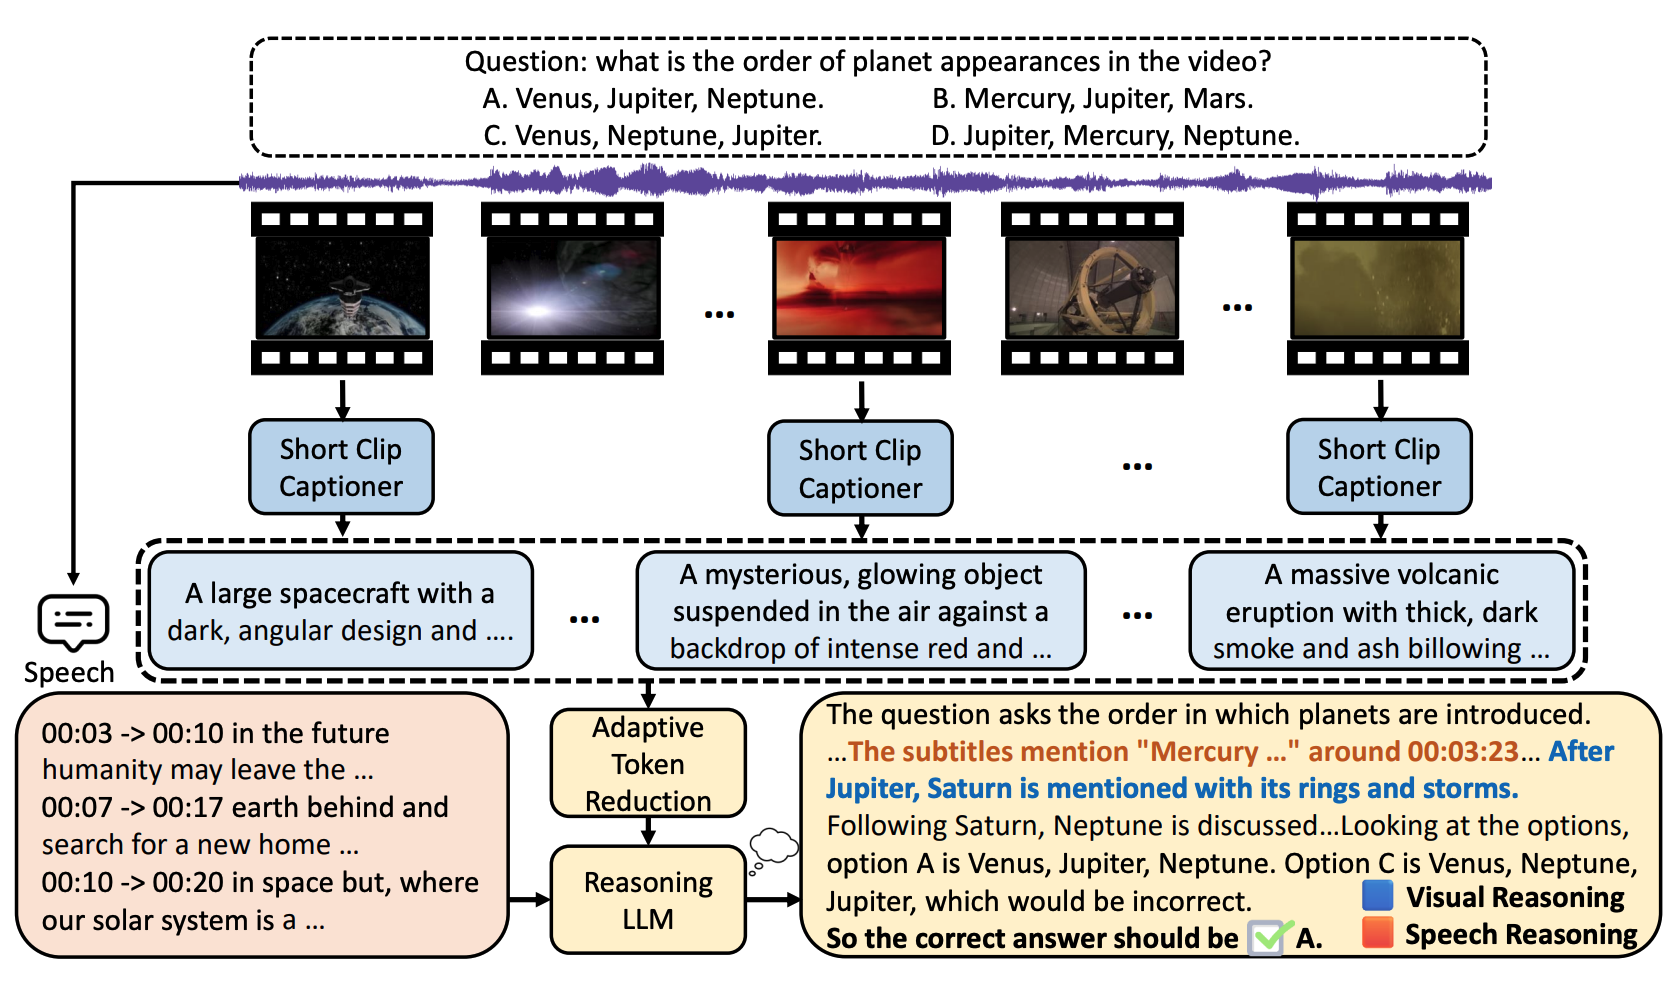
SiLVR: A Simple Language-based Video Reasoning FrameworkCe Zhang*, Yan-Bo Lin*, Ziyang Wang, Mohit Bansal, Gedas Bertasius TMLR 2026 arxiv / code / We present SiLVR, a Simple Language-based Video Reasoning framework that decomposes complex video understanding into two stages. In the first stage, SiLVR transforms raw video into language-based representations using multisensory inputs, such as short clip captions and audio/speech subtitles. In the second stage, language descriptions are fed into a powerful reasoning LLM to solve complex video-language understanding tasks. SiLVR has been awarded the 1st in Track 1B: Multi-Discipline Lecture Understanding at CVPR 2025 Multimodal Video Agent Workshop |
|
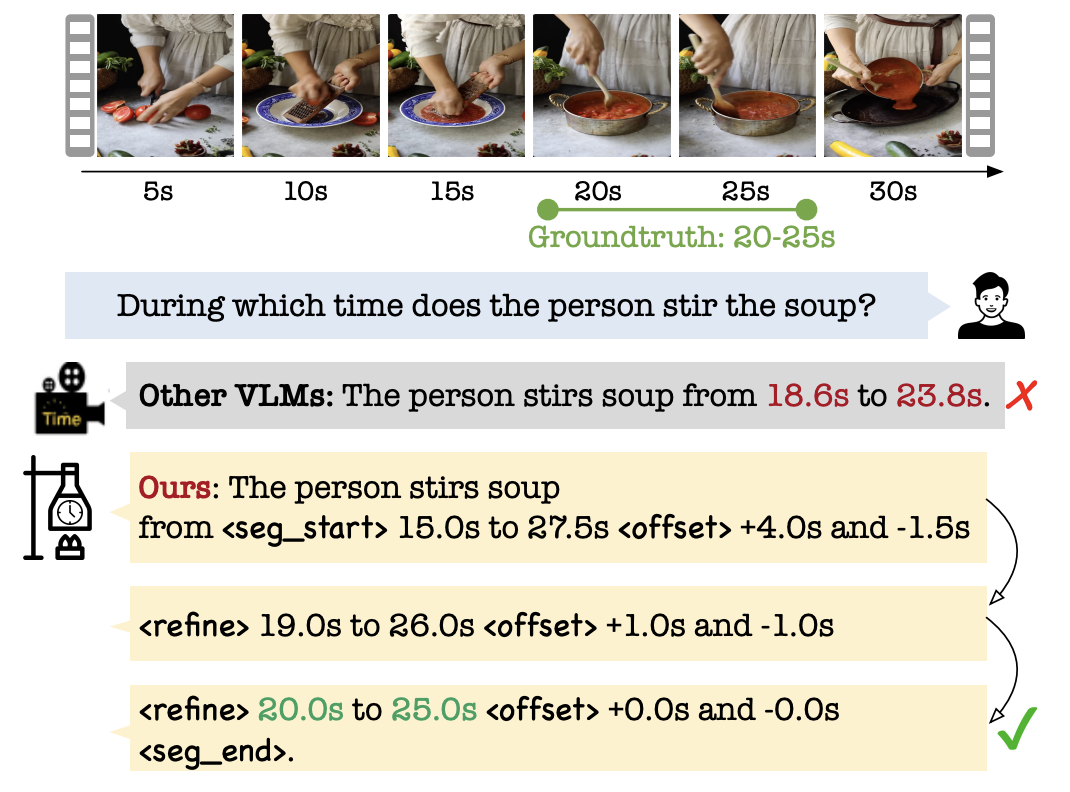
TimeRefine: Temporal Grounding with Time Refining Video LLMXizi Wang, Feng Cheng, Ziyang Wang, Huiyu Wang, Md Mohaiminul Islam, Lorenzo Torresani, Mohit Bansal, Gedas Bertasius, David Crandall WACV 2026 arxiv / In this work, we propose TimeRefine to enhance the capability of Video LLMs in performing temporal grounding. Unlike previous approaches that focus on data curation or architectural enhancements, we focus on refining the learning objective to better suit temporal grounding within the Video LLM framework. |
|
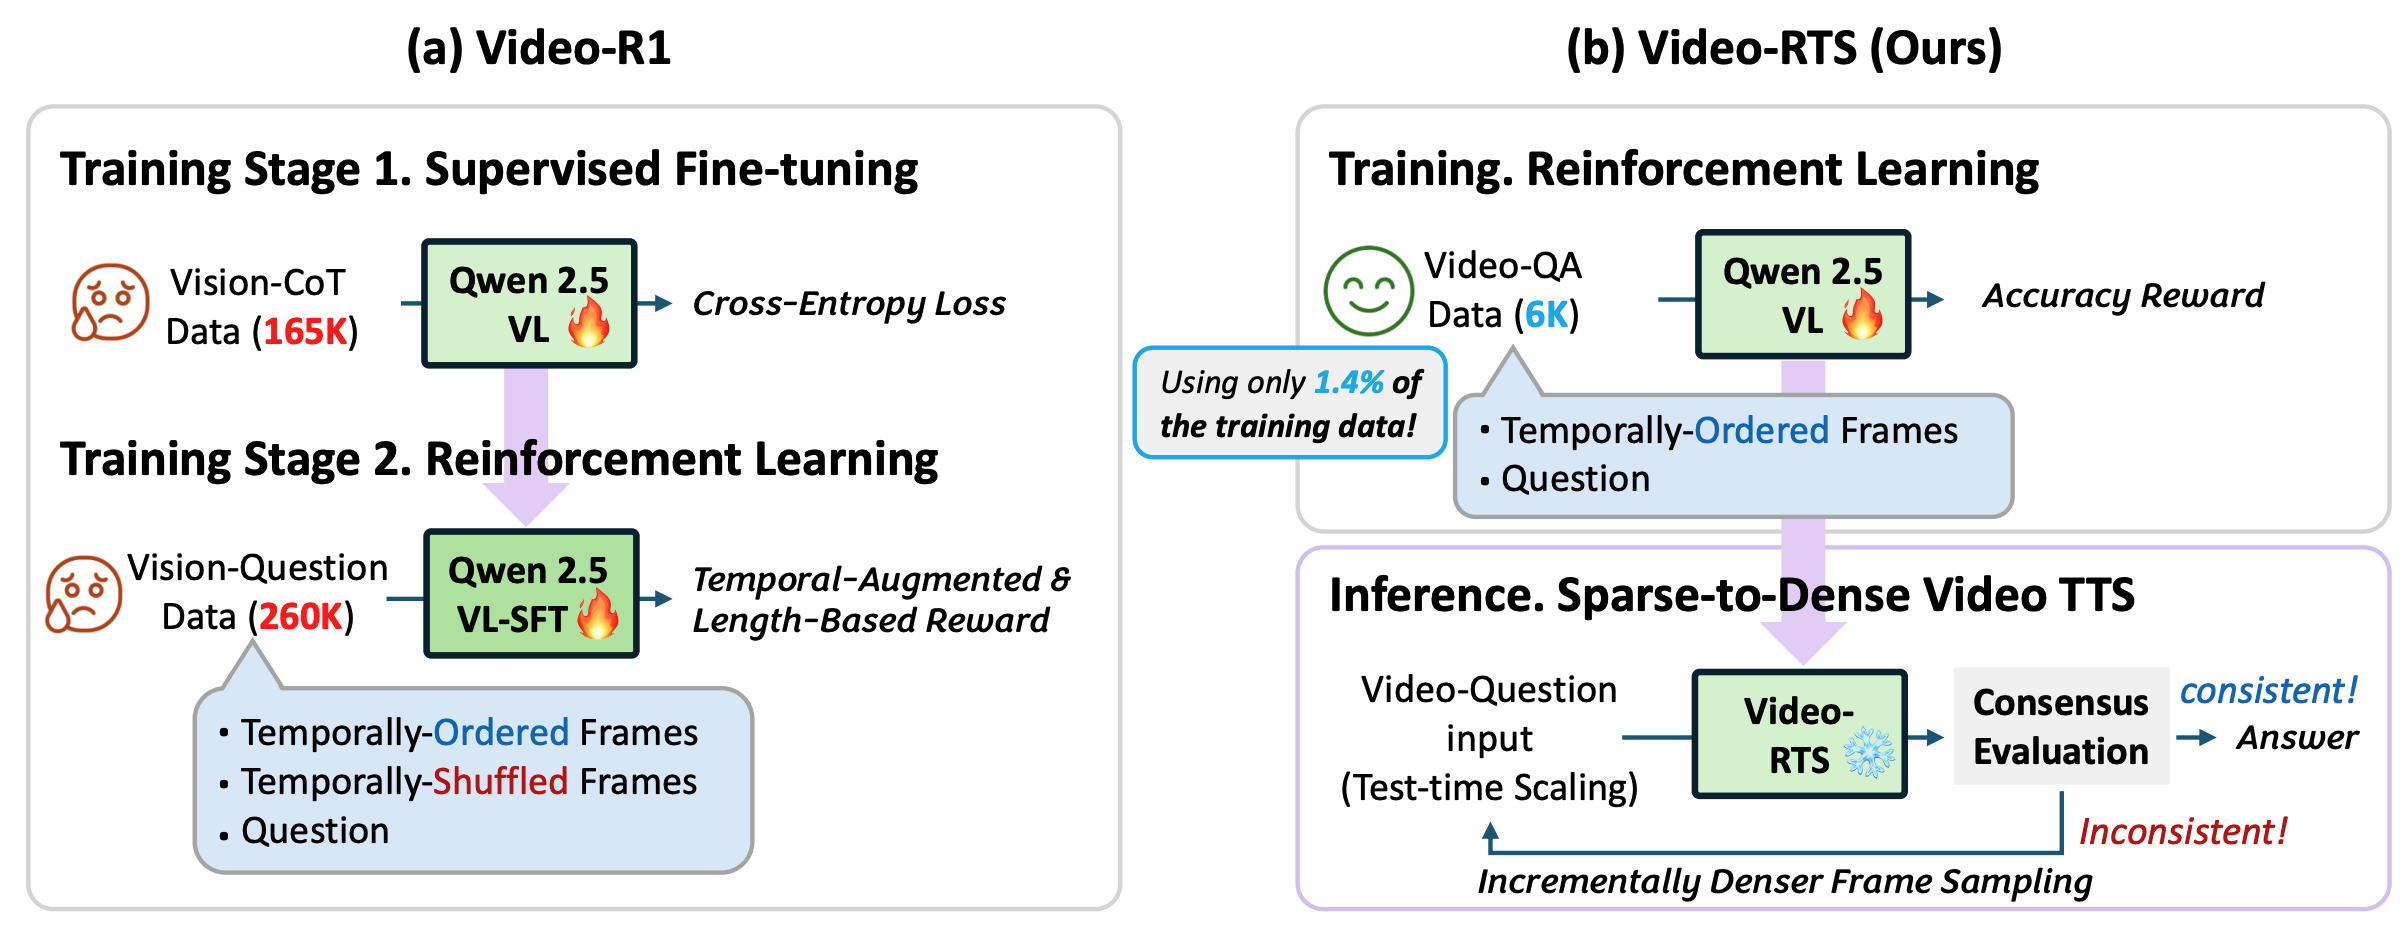
Video-RTS: Rethinking Reinforcement Learning and Test-Time Scaling for Efficient and Enhanced Video ReasoningZiyang Wang*,Jaehong Yoon*, Shoubin Yu, Md Mohaiminul Islam, Gedas Bertasius, Mohit Bansal EMNLP 2025 Main arxiv / code / We introduce Video-RTS, a new approach to improve video reasoning capability with drastically improved data efficiency by combining data-efficient RL with a video-adaptive test-time scaling (TTS) strategy. |
|
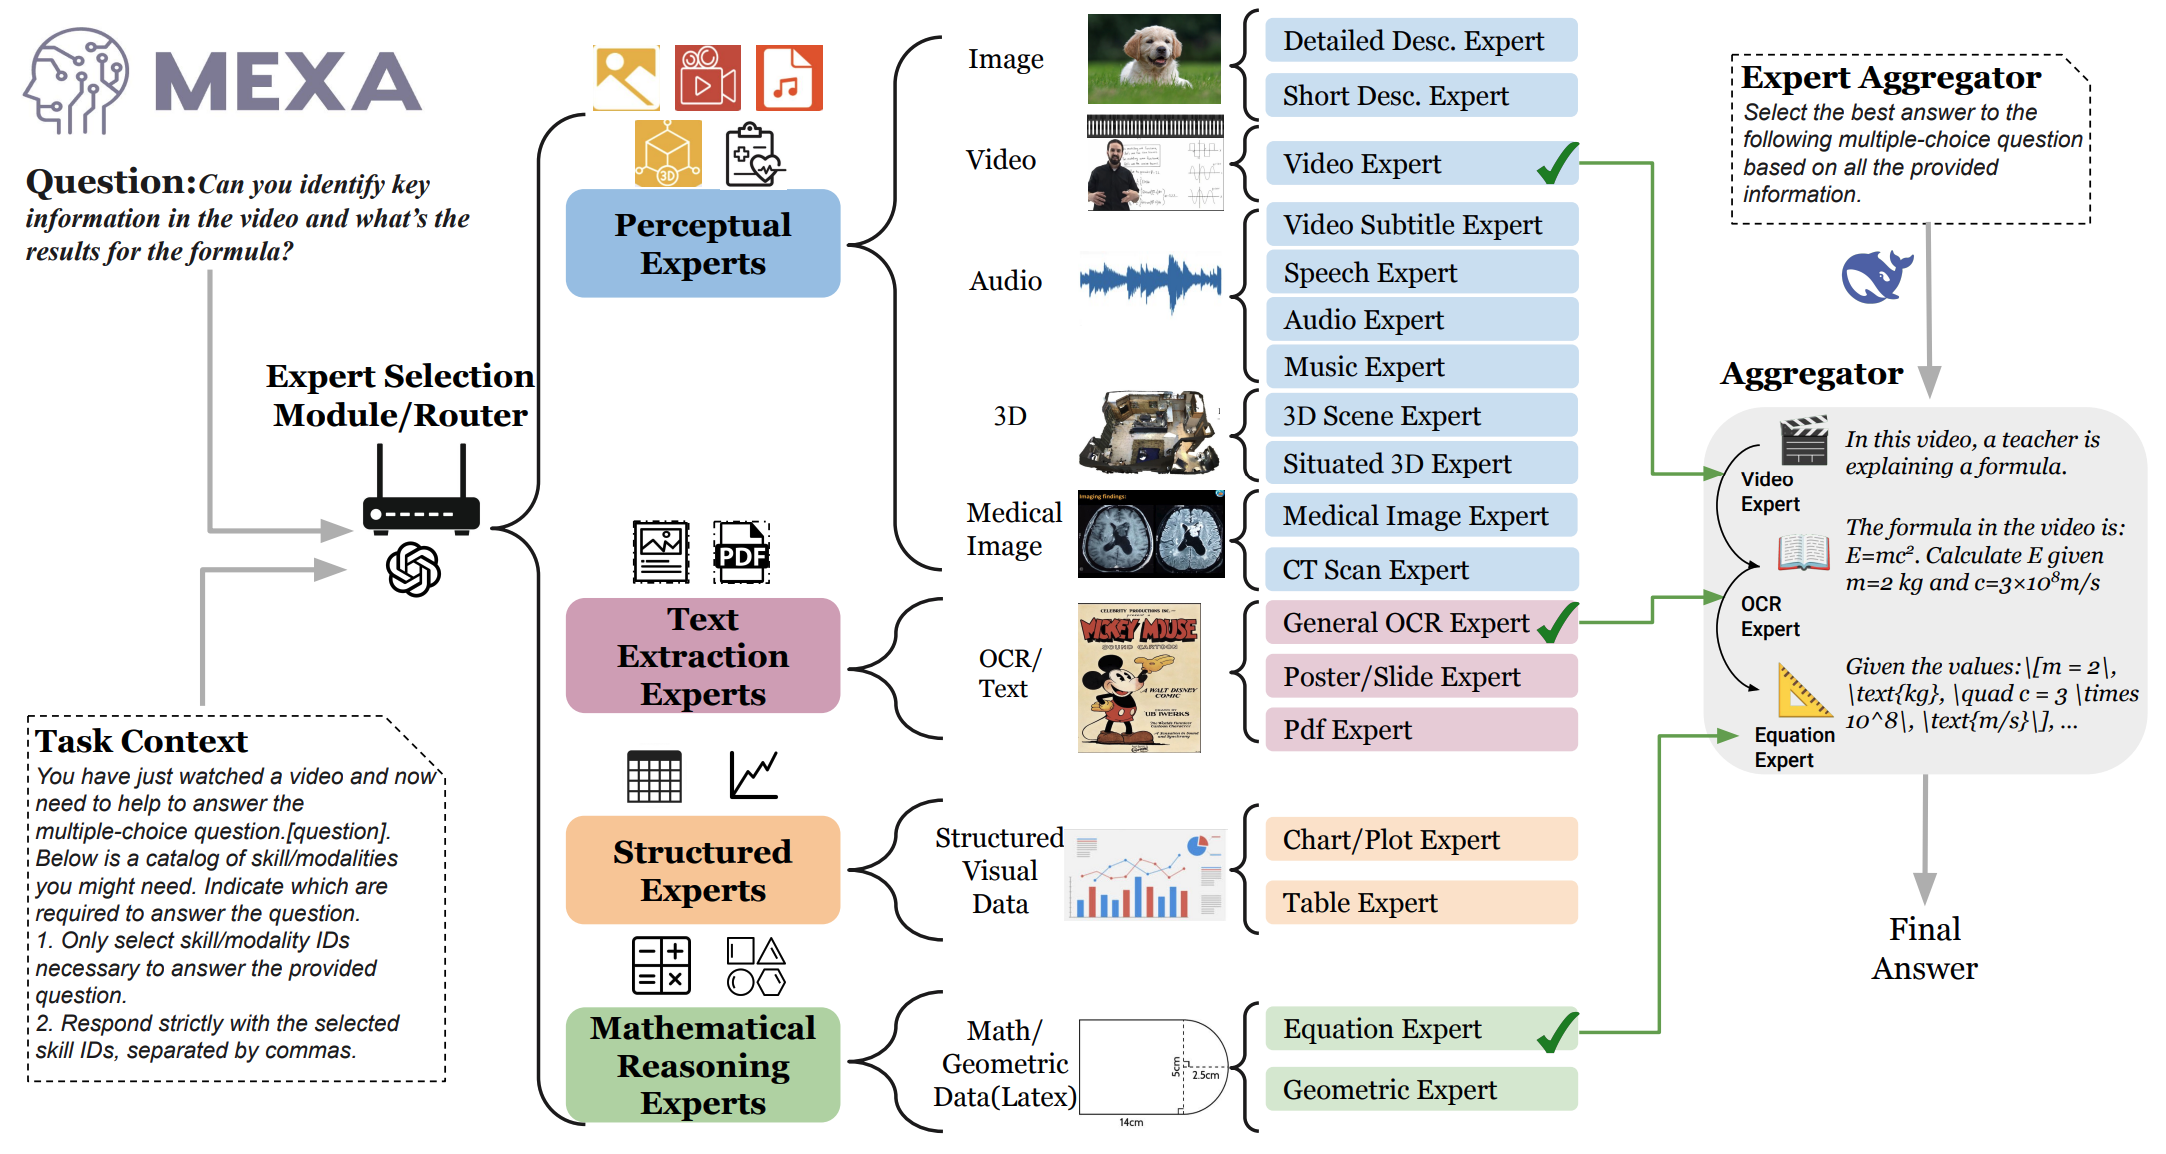
MEXA: Towards General Multimodal Reasoning with Dynamic Multi-Expert AggregationShoubin Yu*, Yue Zhang*, Ziyang Wang, Jaehong Yoon, Mohit Bansal EMNLP 2025 Findings arxiv / code / We introduce MEXA, a training-free framework that performs modality- and task-aware aggregation of multiple expert models to enable effective multimodal reasoning across diverse and distinct domains. |
|
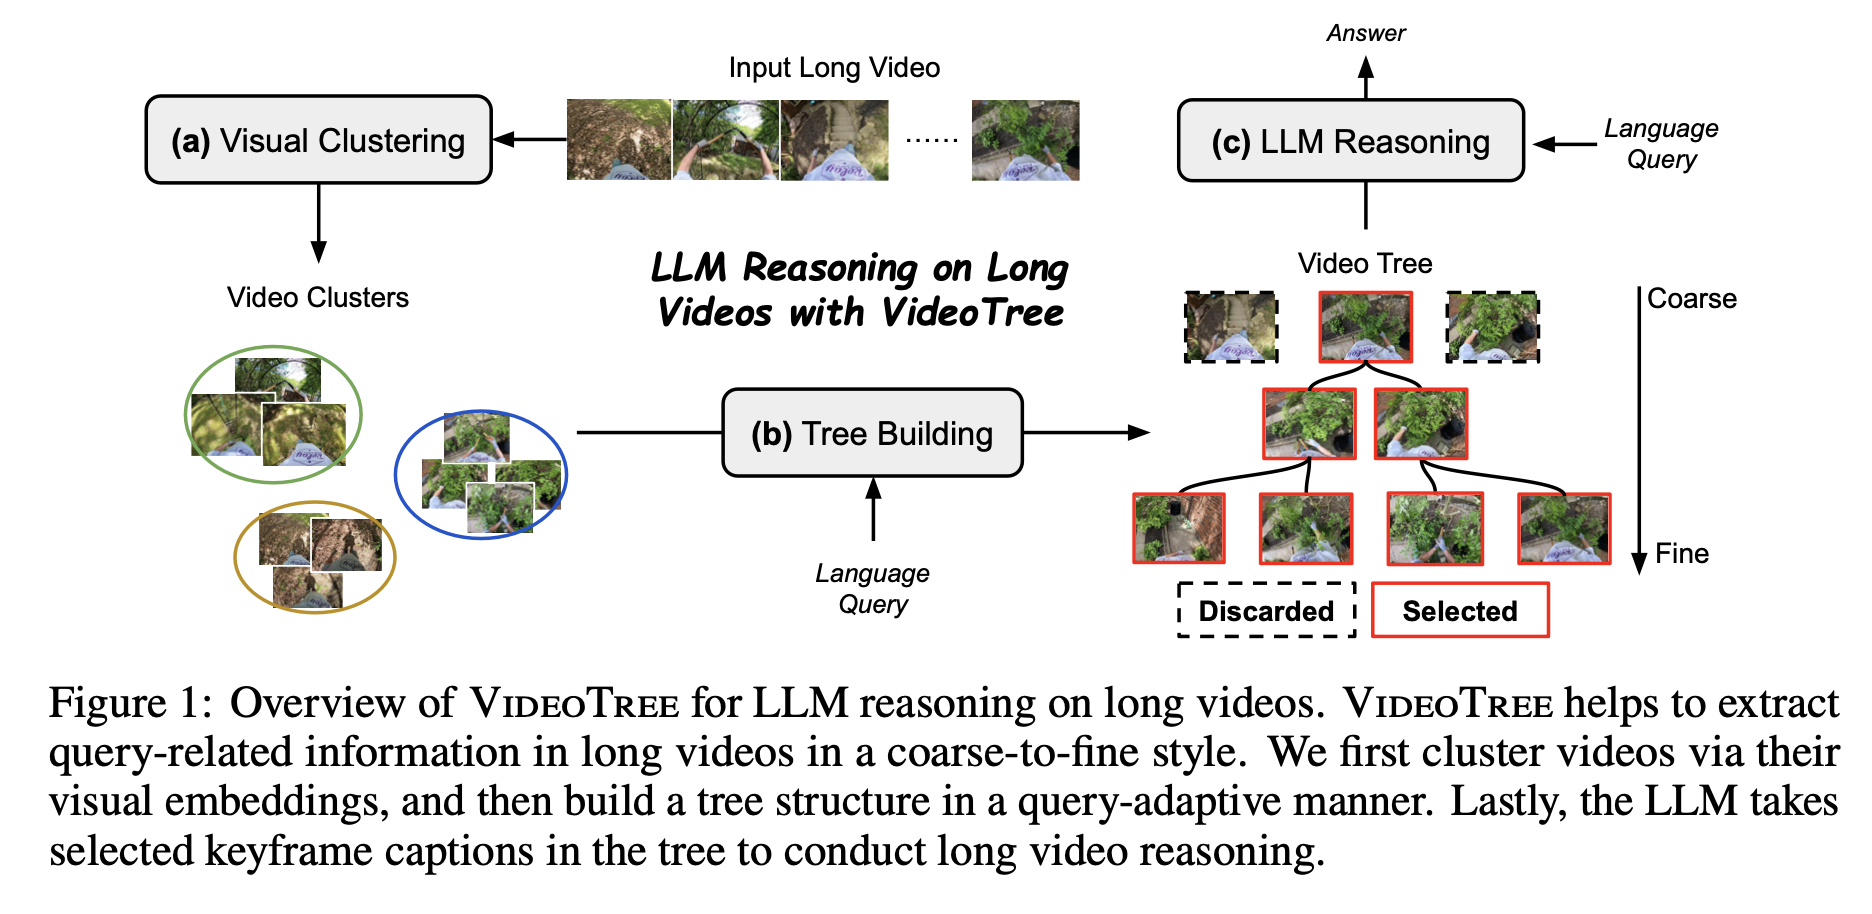
VideoTree: Adaptive Tree-based Video Representation for LLM Reasoning on Long VideosZiyang Wang*, Shoubin Yu*, Elias Stengel-Eskin*, Jaehong Yoon, Feng Cheng, Gedas Bertasius, Mohit Bansal CVPR 2025 arxiv / code / We introduce VideoTree, a query-adaptive and hierarchical framework for long-video understanding with LLMs. Specifically, VideoTree dynamically extracts query-related information from the input video and builds a tree-based video representation for LLM reasoning. |
|
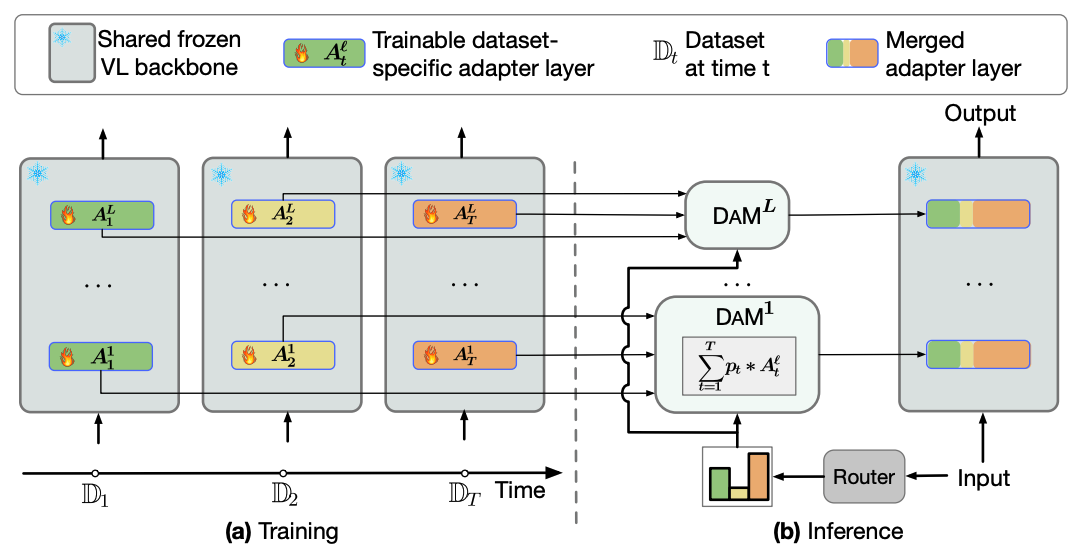
DAM: Dynamic Adapter Merging for Continual Video QA LearningFeng Cheng*, Ziyang Wang*, Yi-Lin Sung, Yan-Bo Lin, Mohit Bansal, Gedas Bertasius WACV 2025 arxiv / code / In this work, we investigate the challenging and relatively unexplored problem of rehearsal-free domain-incremental VidQA learning. Our proposed DAM framework outperforms existing state-of-the-art by 9.1% with 1.9% less forgetting on a benchmark with six distinct video domains. |
|
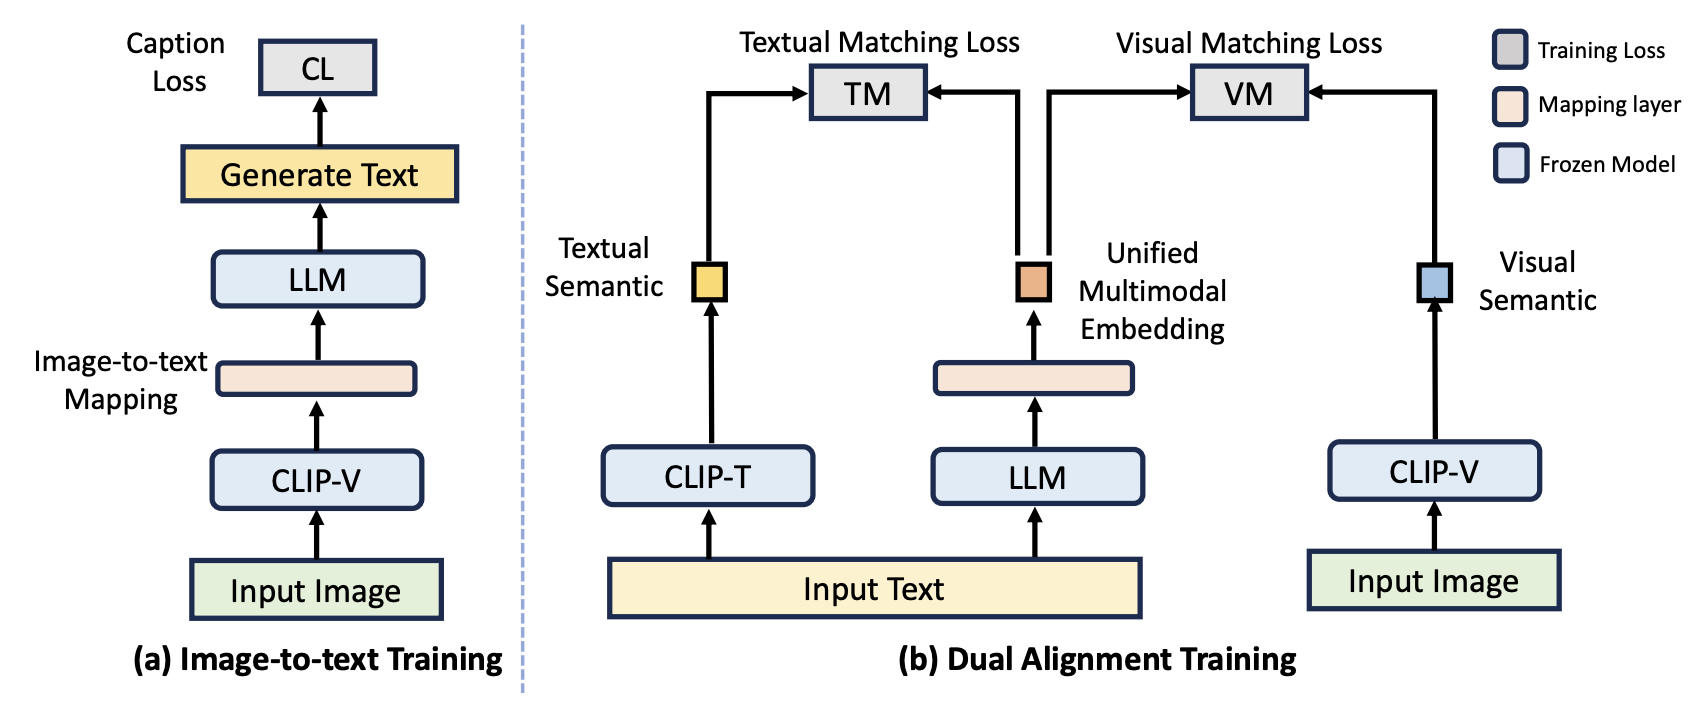
Unified Embeddings for Multimodal Retrieval via Frozen LLMsZiyang Wang, Heba Elfardy, Markus Dreyer, Kevin Small, Mohit Bansal EACL 2024 Findings In this work, We present Unified Embeddings for Multimodal Retrieval (UNIMUR), a simple but effective approach that embeds multimodal inputs and retrieves visual and textual outputs via frozen Large Language Models (LLMs). Specifically, UNIMUR jointly retrieves multimodal outputs via unified multimodal embedding and applies dual alignment training to account for both visual and textual semantics. |
|
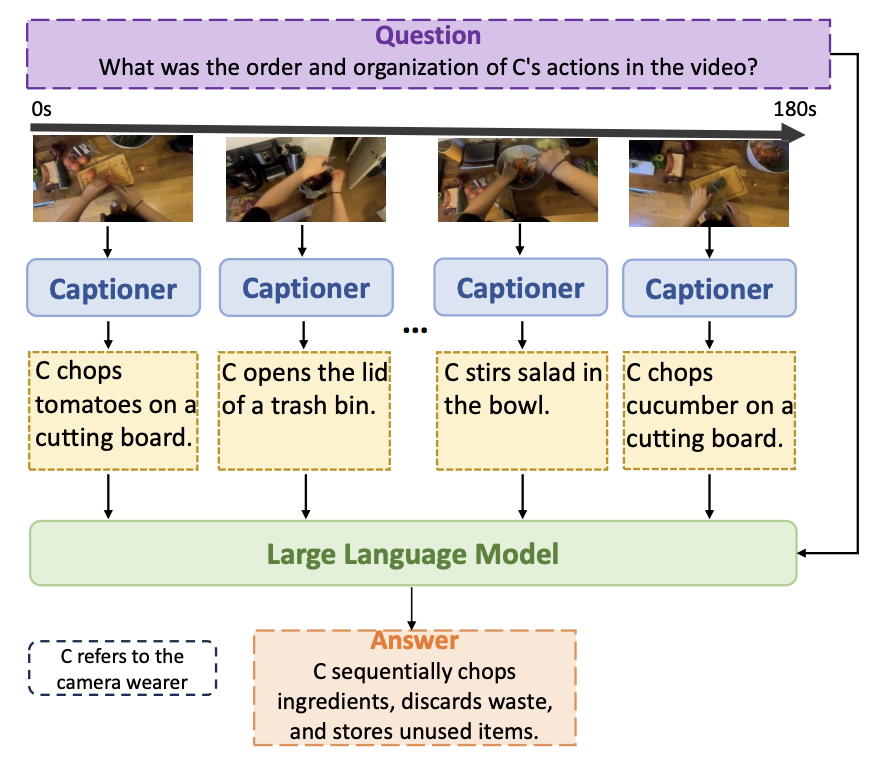
A Simple LLM Framework for Long-Range Video Question-AnsweringCe Zhang, Taixi Lu, Md Mohaiminul Islam, Ziyang Wang, Shoubin Yu, Mohit Bansal, Gedas Bertasius EMNLP 2024 Main arxiv / code / We present LLoVi, a language-based framework for long-range video question-answering (LVQA). Unlike prior long-range video understanding methods, which are often costly and require specialized long-range video modeling design (e.g., memory queues, state-space layers, etc.), our approach uses a frame/clip-level visual captioner coupled with a Large Language Model (GPT-3.5, GPT-4) leading to a simple yet surprisingly effective LVQA framework. |
|
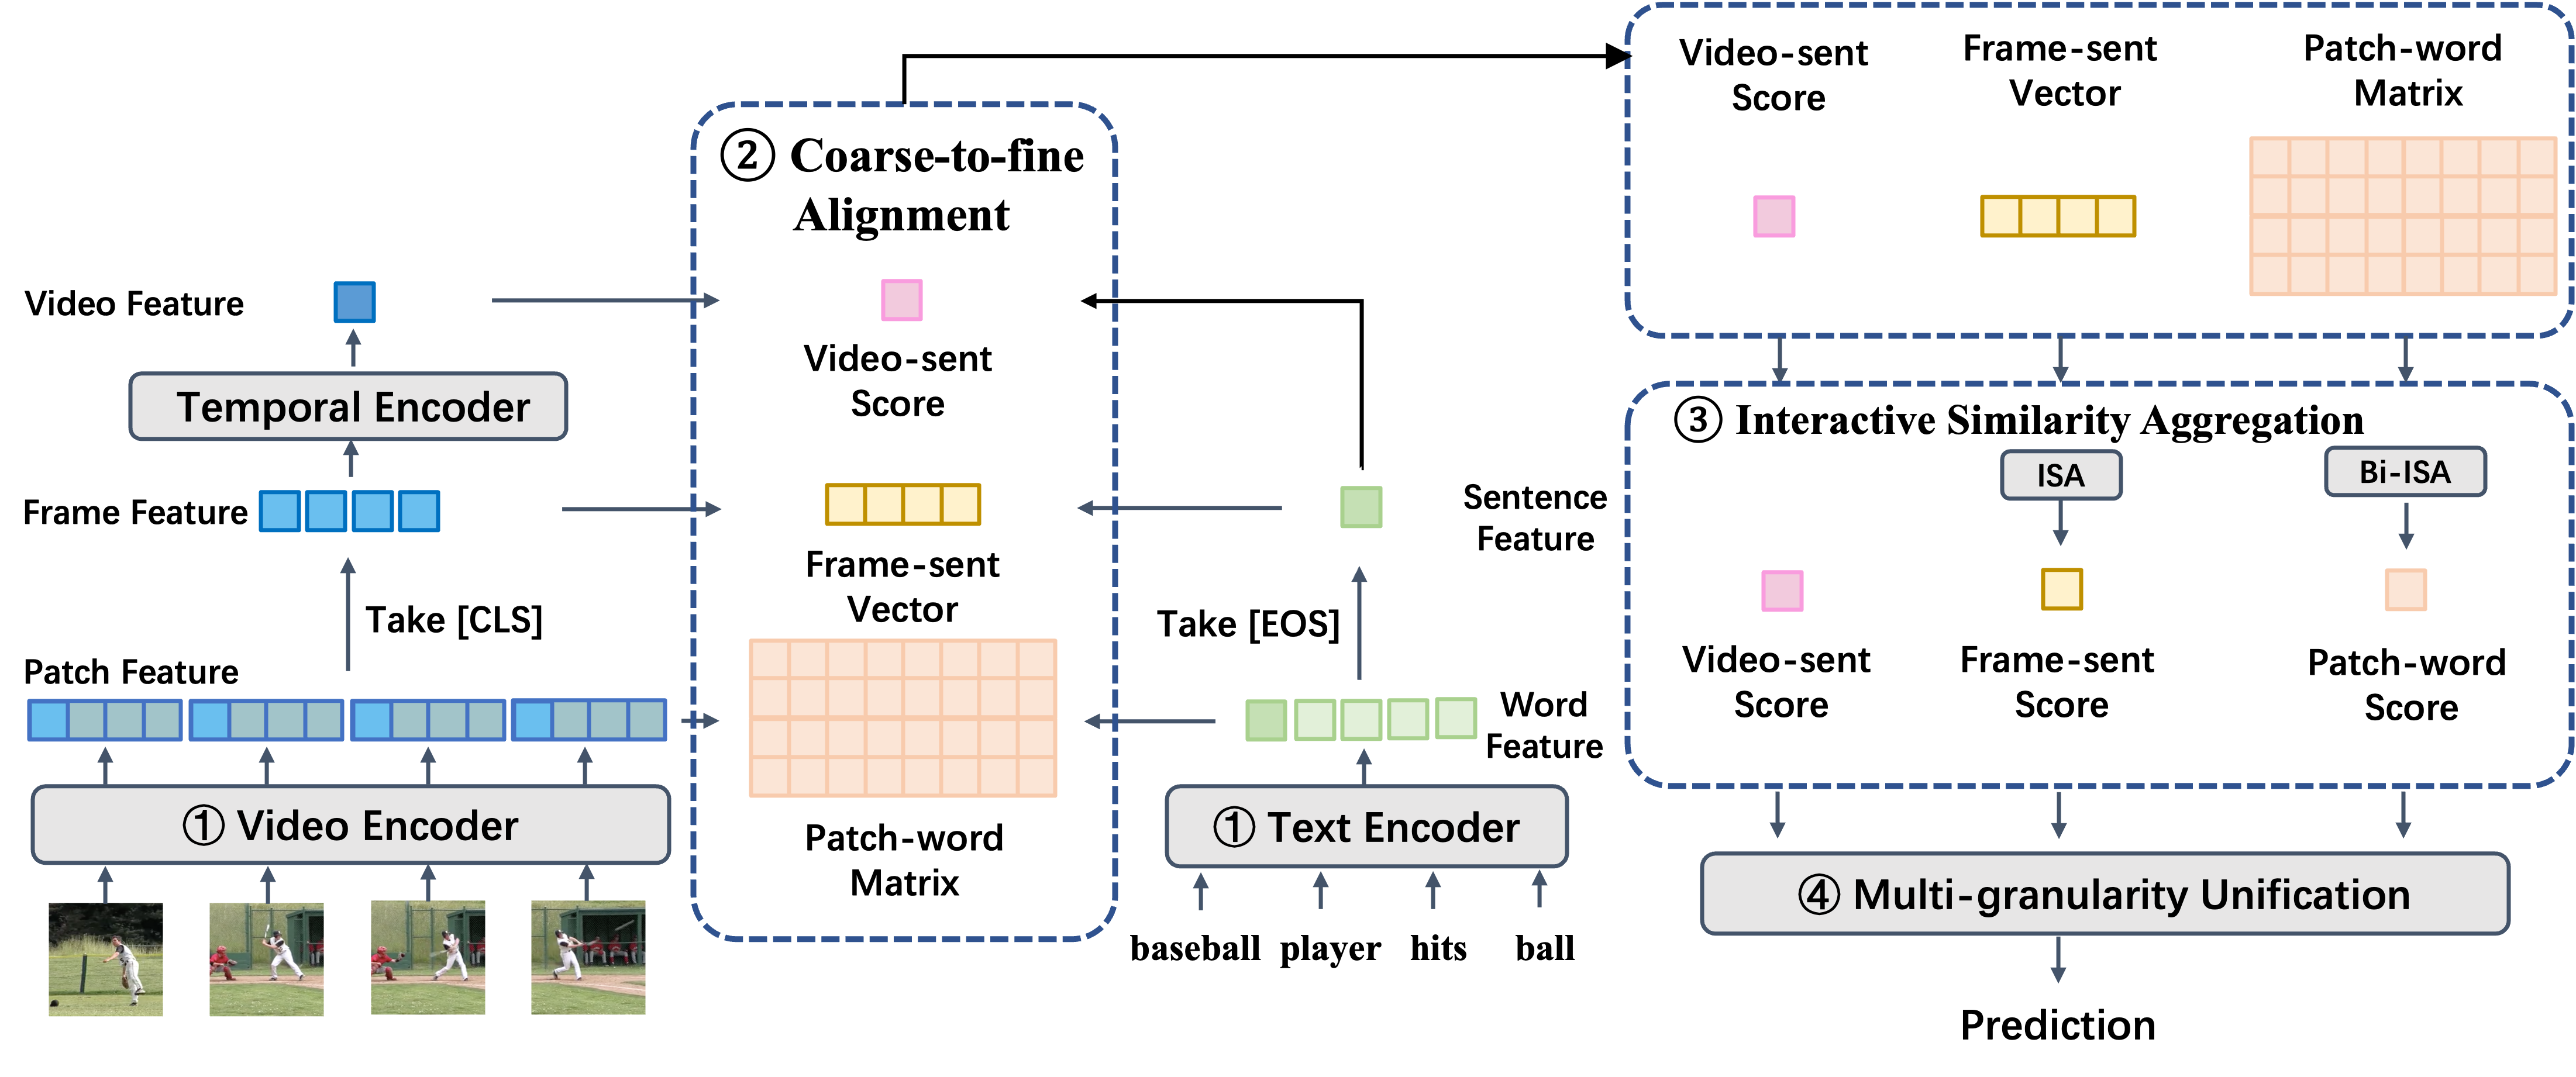
Unified Coarse-to-Fine Alignment for Video-Text RetrievalZiyang Wang, Yi-Lin Sung, Feng Cheng, Gedas Bertasius, Mohit Bansal ICCV 2023 arxiv / code / UCoFiA captures the cross-modal similarity information at different granularity levels(video-sentence, frame-sentence, pixel-word) and unifies multi-level alignments for video-text retrieval. |
|
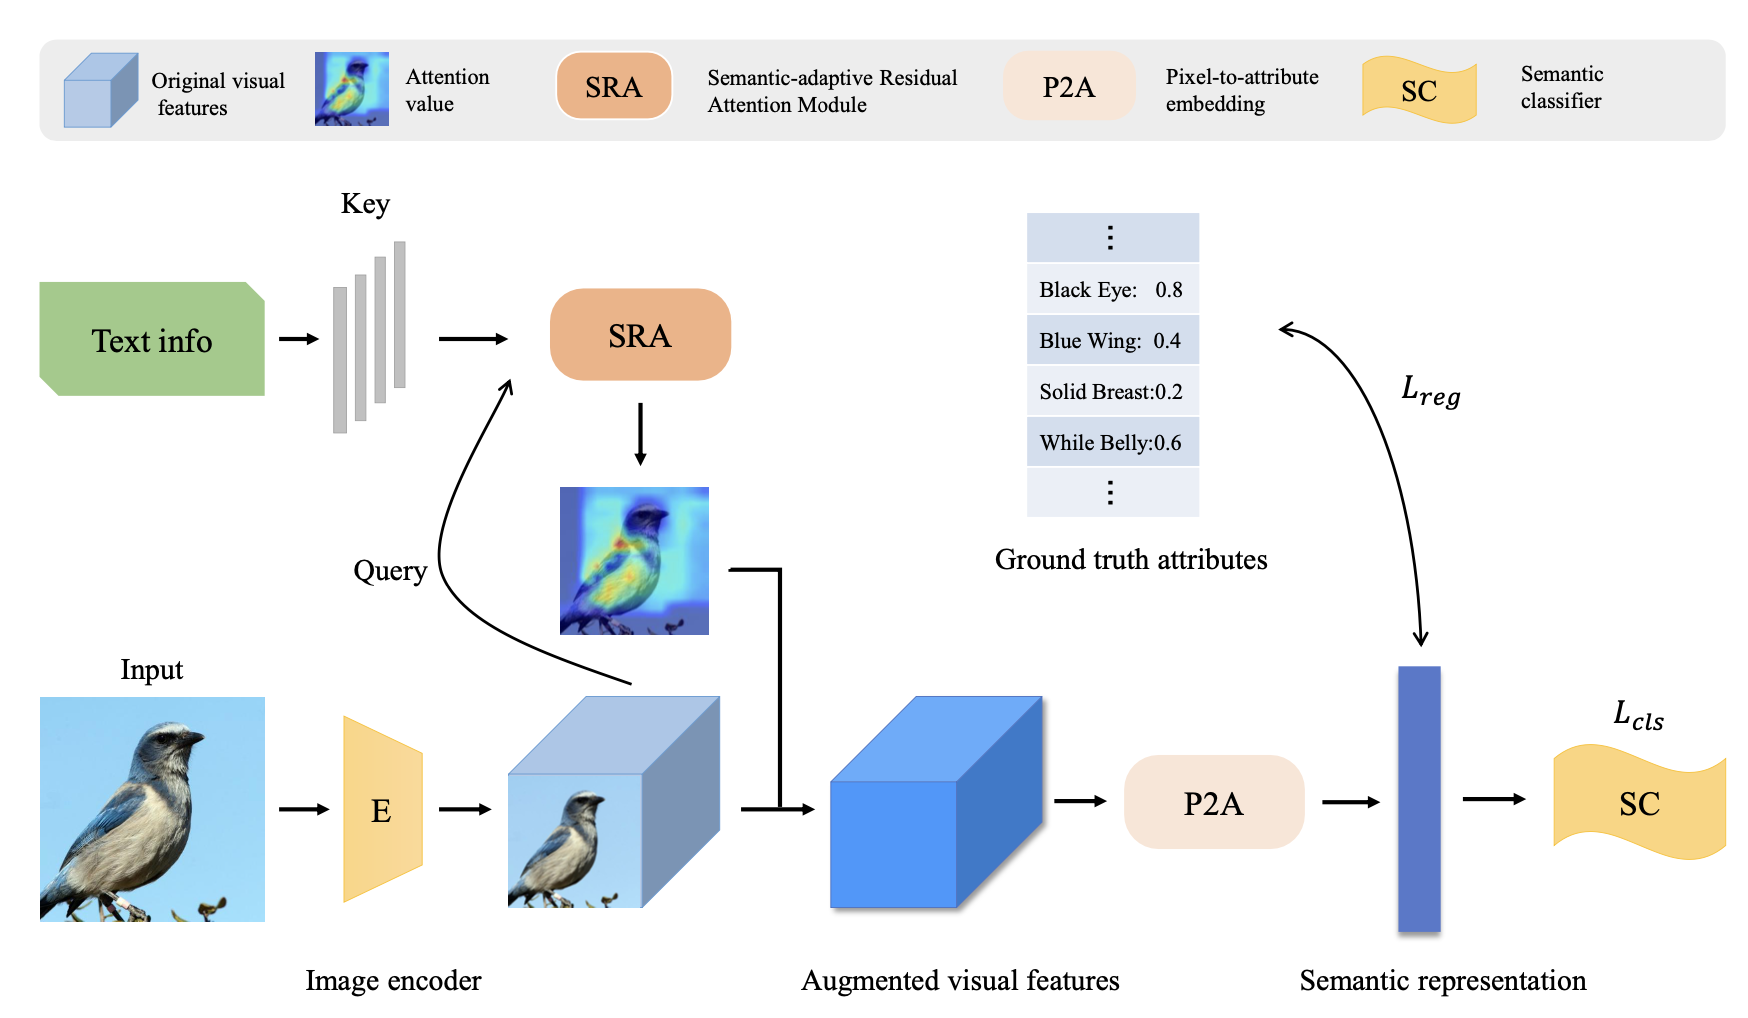
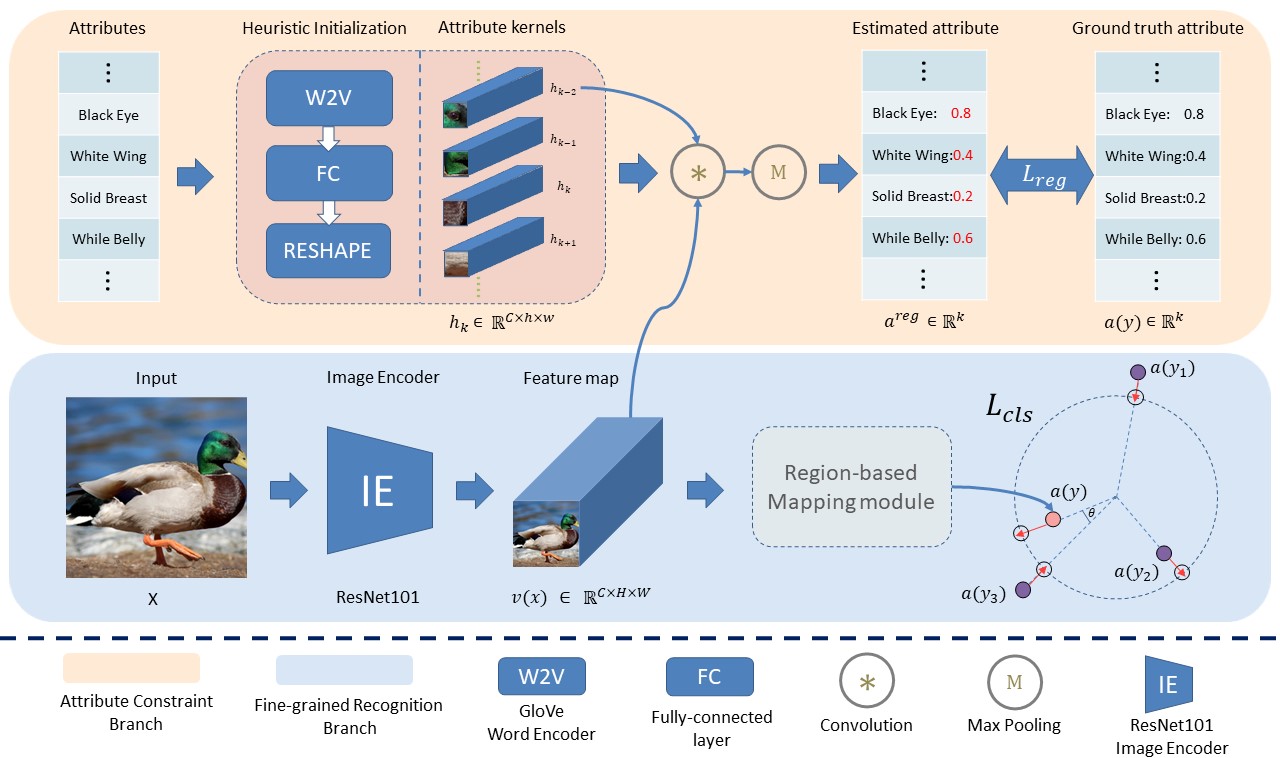
Language-Augmented Pixel Embedding for Generalized Zero-shot LearningZiyang Wang, Yunhao Gou, Jingjing Li, Lei Zhu, Heng Tao Shen TCSVT 2022 In this paper, we propose a novel GZSL framework named Language-Augmented Pixel Embedding (LAPE), which directly maps the image pixels to the semantic attributes with cross-modal guidance. |
|
Region Semantically Aligned Network for Zero-Shot LearningZiyang Wang*, Yunhao Gou*, Jingjing Li, Yu Zhang, Yang Yang CIKM 2021 (Long Oral) arxiv / We propose a novel ZSL framework named Region Semantically Aligned Network (RSAN), which transfers region-attribute alignment from seen classes to unseen classes. |
Honors & ServiceBloomberg Data Science Ph.D. Fellowship, Bloomberg L.P., March 2026 — recognized for my research in long-context multimodal understanding and multimodal agents. Co-organizer of the Transformers for Vision (T4V) Workshop @ CVPR 2025 & 2026 (program committee member in 2023 & 2024). Reviewer for ECCV, ICLR, CVPR, COLM, WACV, ACL Rolling Reviews, and IJCV. |
HobbyI am a die-heart Arsenal and Tar Heel fan. |
|
Design and source code from Leonid Keselman's website, thanks! |